AI innovation. No compromises

  • Faster than virtualized GPUs~20%
  • EdgeLink optics1.6T
  • Below OEM optics40%+
  • Bandwidth penaltiesZero
NVIDIA systems

From H200 to Vera Rubin

Bare-metal NVIDIA GPUs with compute-centric pricing, from model training to global inference. One platform, full control, no bandwidth penalties.

Compare systems

Every system runs single-tenant on bare metal, with Kubernetes, Slurm or your own stack on top.

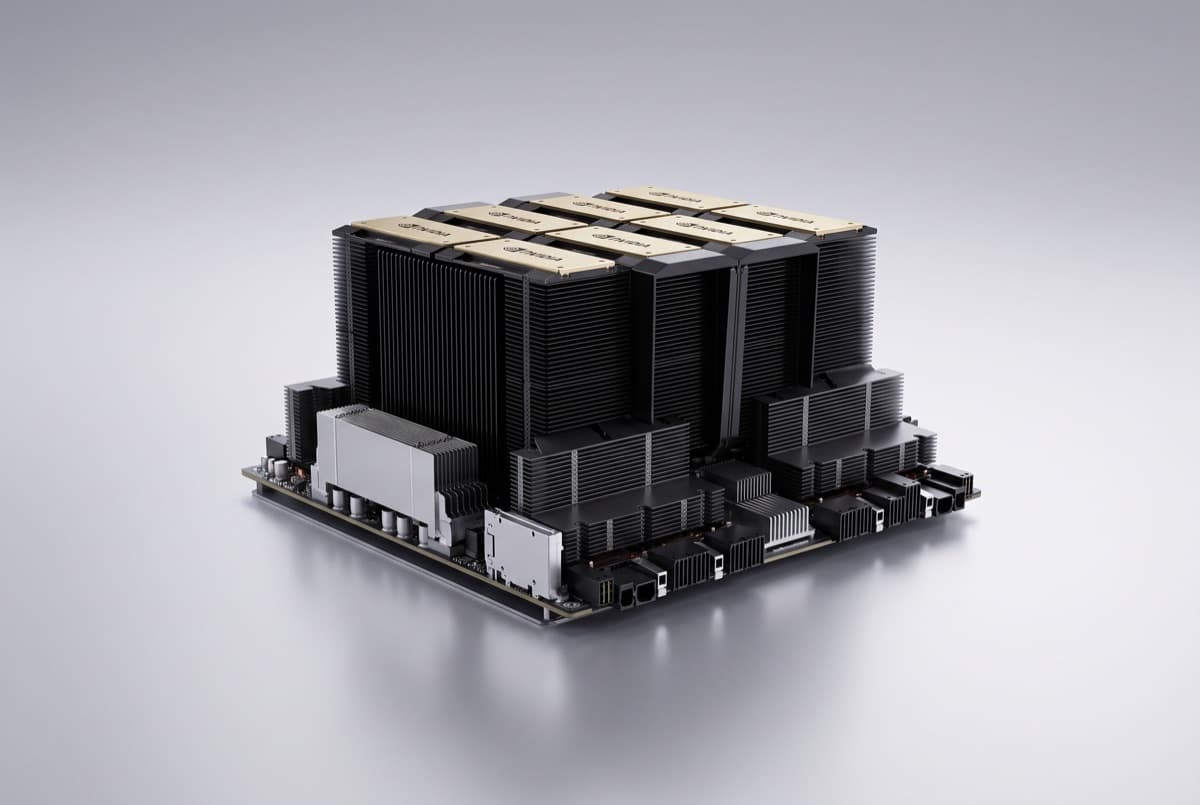
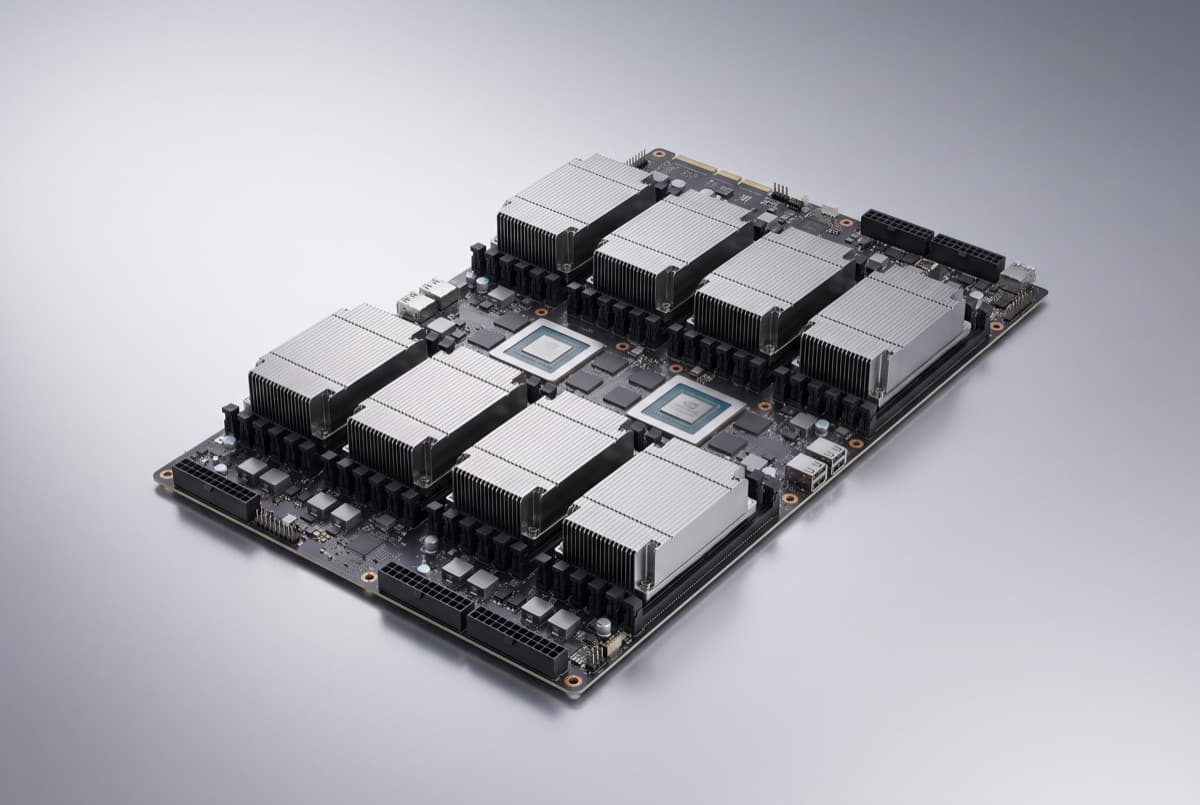
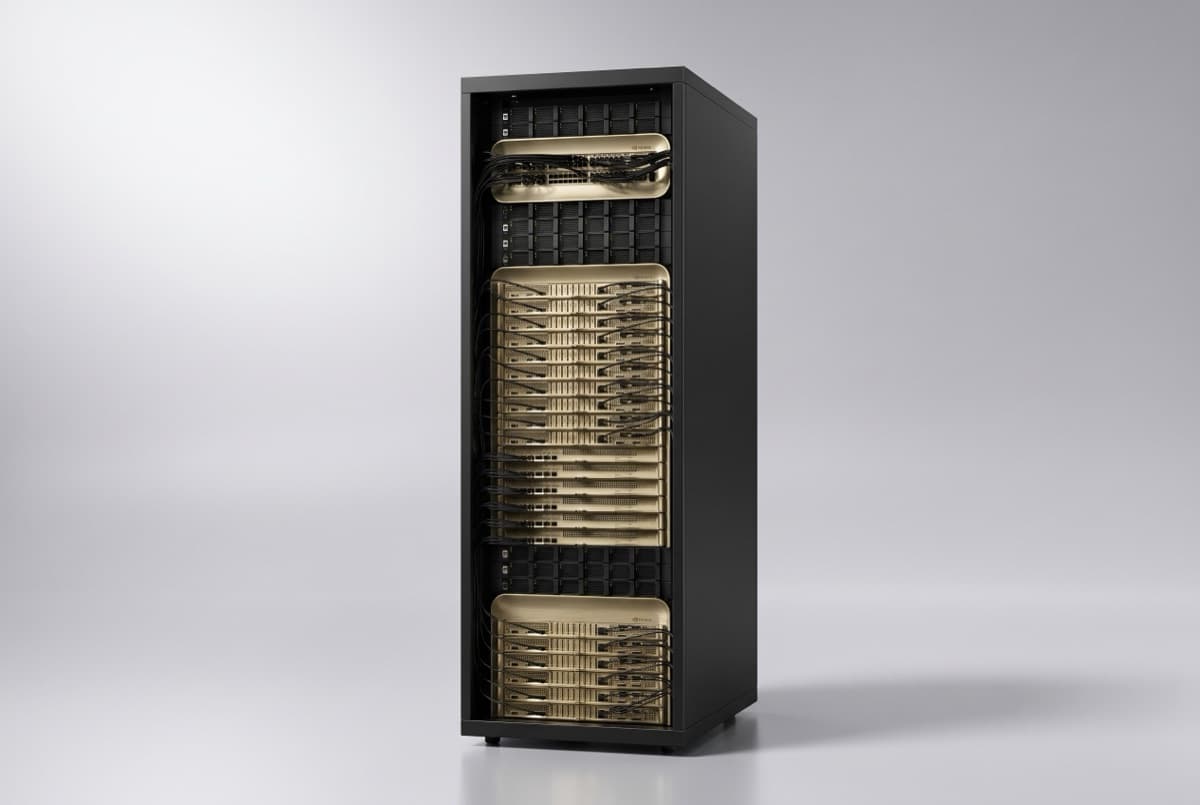
H200NVIDIA HopperIn stockB200NVIDIA BlackwellIn stockB300NVIDIA HGX · Blackwell UltraIn stockGB300 NVL72NVIDIA MGX · Grace Blackwell UltraReserveVera Rubin NVL72NVIDIA MGX · Vera RubinReserve
FormSXM5SXMSXMNVL72 rackNVL72 rack
Memory per GPU141 GB HBM3e180 GB HBM3e288 GB HBM3e288 GB HBM3e288 GB HBM4
Bandwidth per GPU4.8 TB/s8 TB/s8 TB/s8 TB/s19.2 TB/s
InterconnectNVLinkNVLinkNVLinkNVLinkNVLink
CPUHost CPUHost CPUHost CPUGraceVera
GPUs per node or rack2–8887272
PriceFrom$4.75per GPU-hourFrom$8.98per GPU-hourFrom$4.10per GPU-hourThrough salesThrough sales
Deploy nowDeploy nowDeploy nowReserve capacityReserve capacity
Why bare metal

Infrastructure without compromise

Direct hardware access, predictable performance and economics that work for AI.

01How it works

From zero to production

Start in minutes on bare-metal GPUs.

  1. 01

    Access

    Bare-metal GPU infrastructure, with no virtualization overhead.

    HypervisorNone

  2. 02

    Deploy

    Models live in minutes, with full kernel-level control.

    Live inMinutes

  3. 03

    Scale

    From the first experiment to production without switching providers.

    One NVLink domainUp to 72 GPUs

  4. 04

    Optimize

    Compute-centric pricing and real-time insight into every run.

    Bandwidth penaltiesZero

Works with
  • PyTorch
  • TensorFlow
  • JAX
  • Kubernetes
  • Slurm
  • Your own stack
02Core offerings

The complete AI stack

Connectivity, compute and deployment: everything AI at scale needs, from one provider.

Get GPU access
Ready for bare-metal AI?

System
Workload *

We use these details only to answer you. See our Privacy Policy.