EdgeAI at the tower—Under 100 ms
Inference at towers and ultra-edge facilities, under 100 ms, with no round trip to a distant cloud.
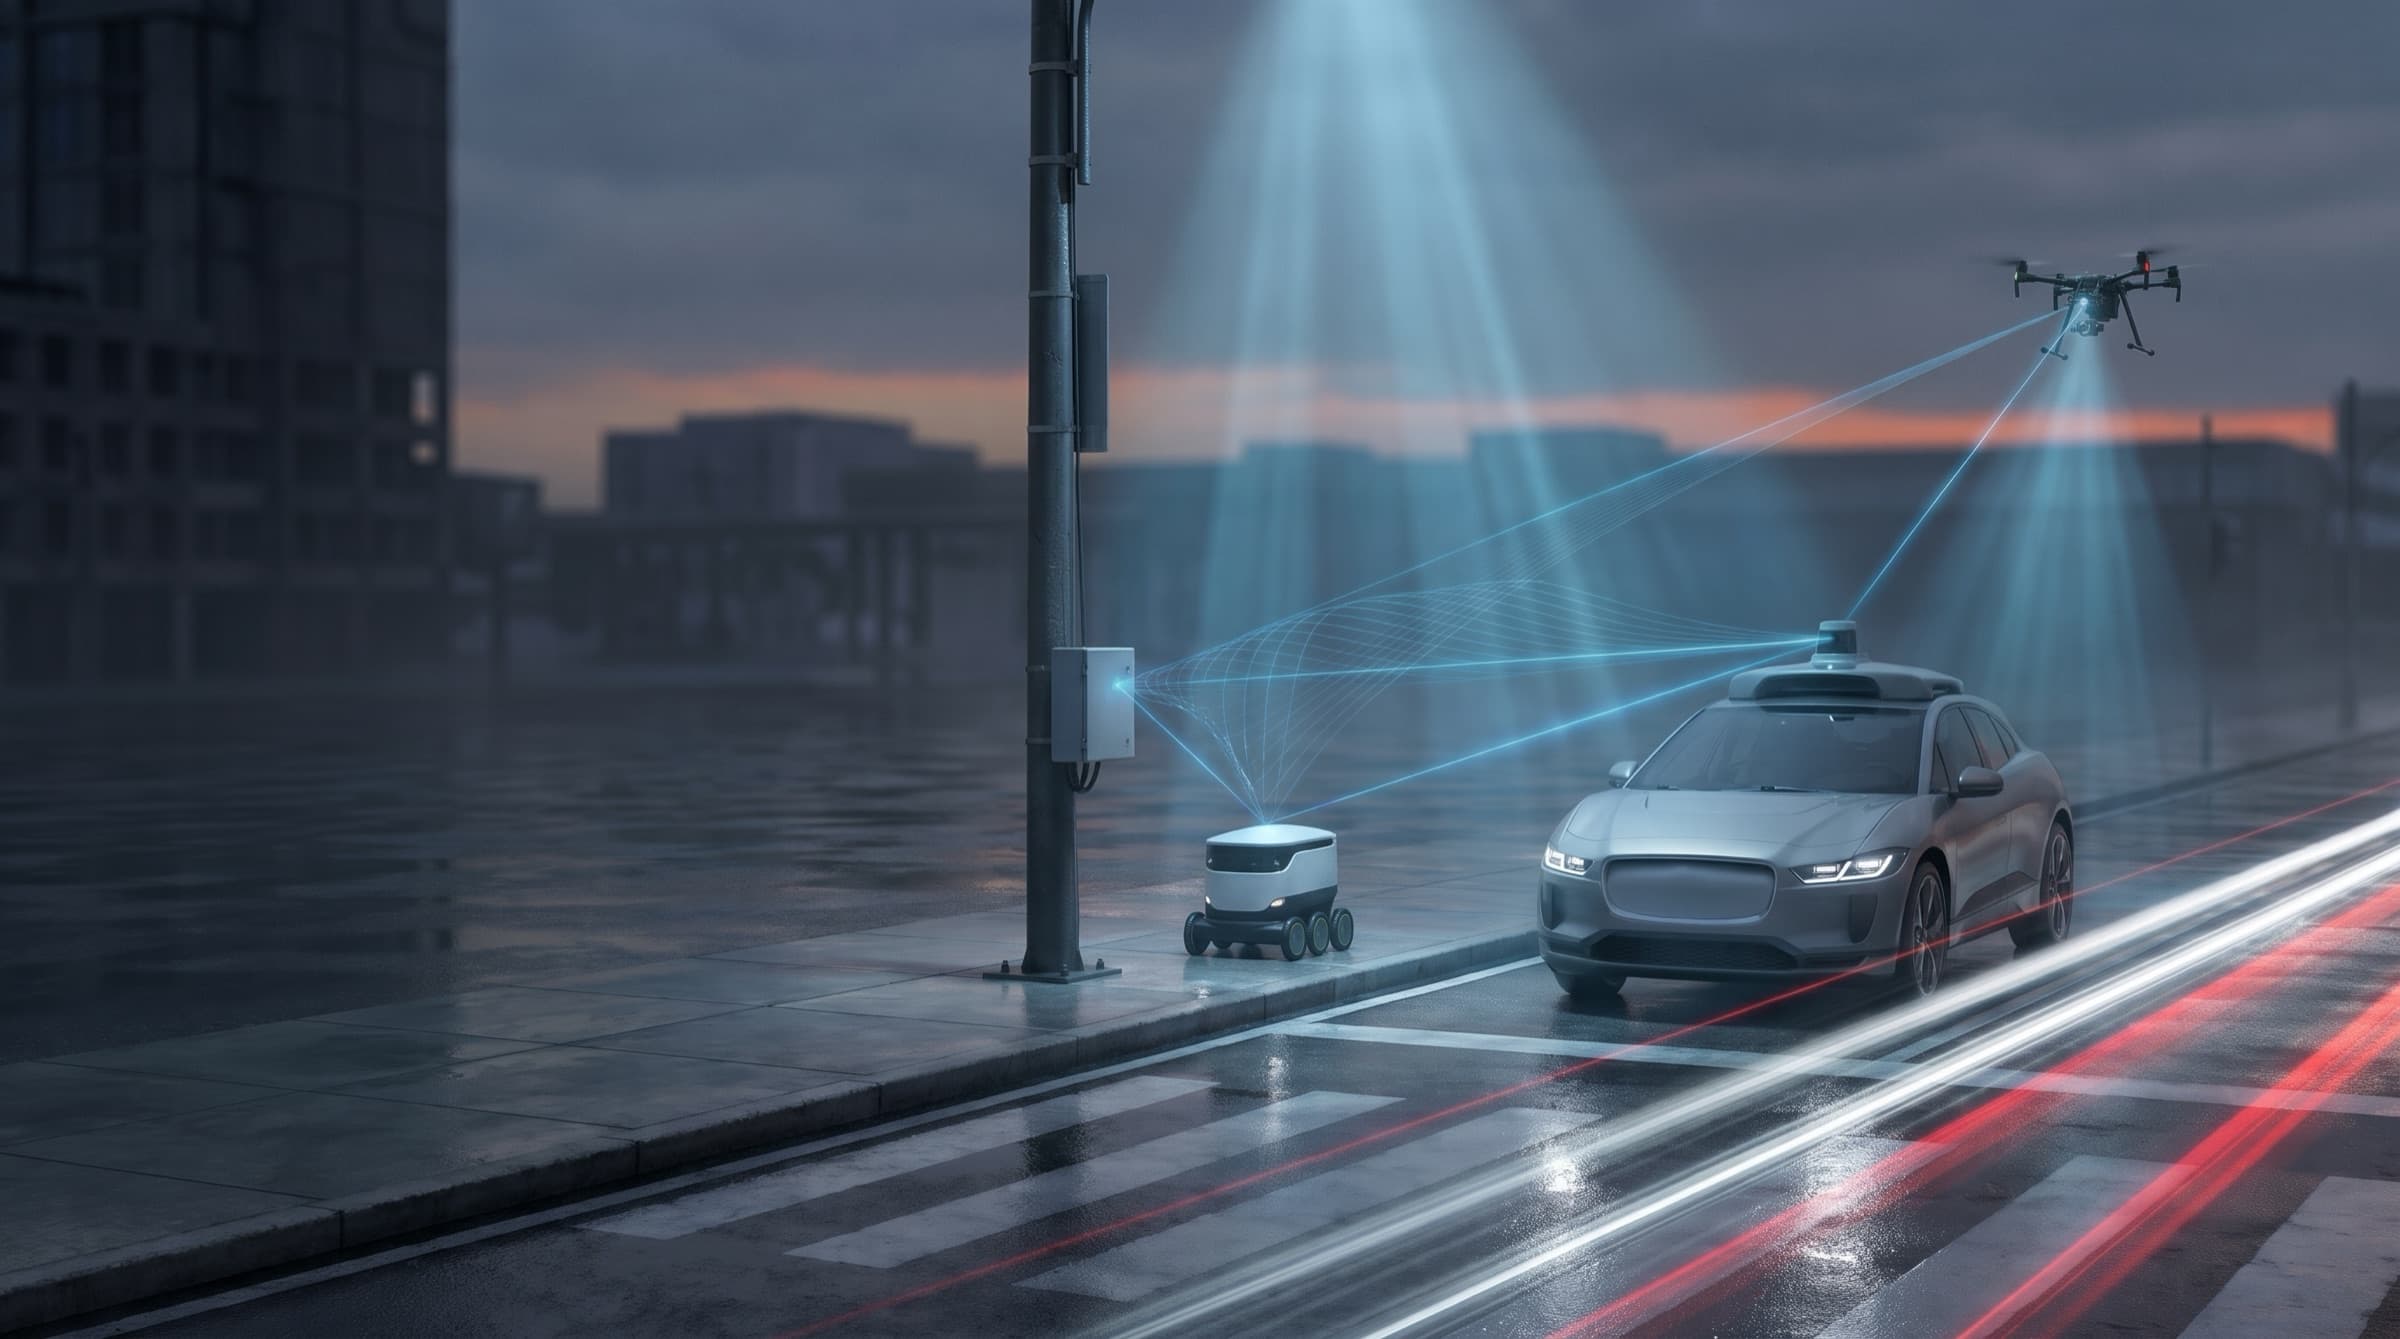
Machines that move need decisions in milliseconds. We run inference at the tower on the corner, and training in the data center behind it.
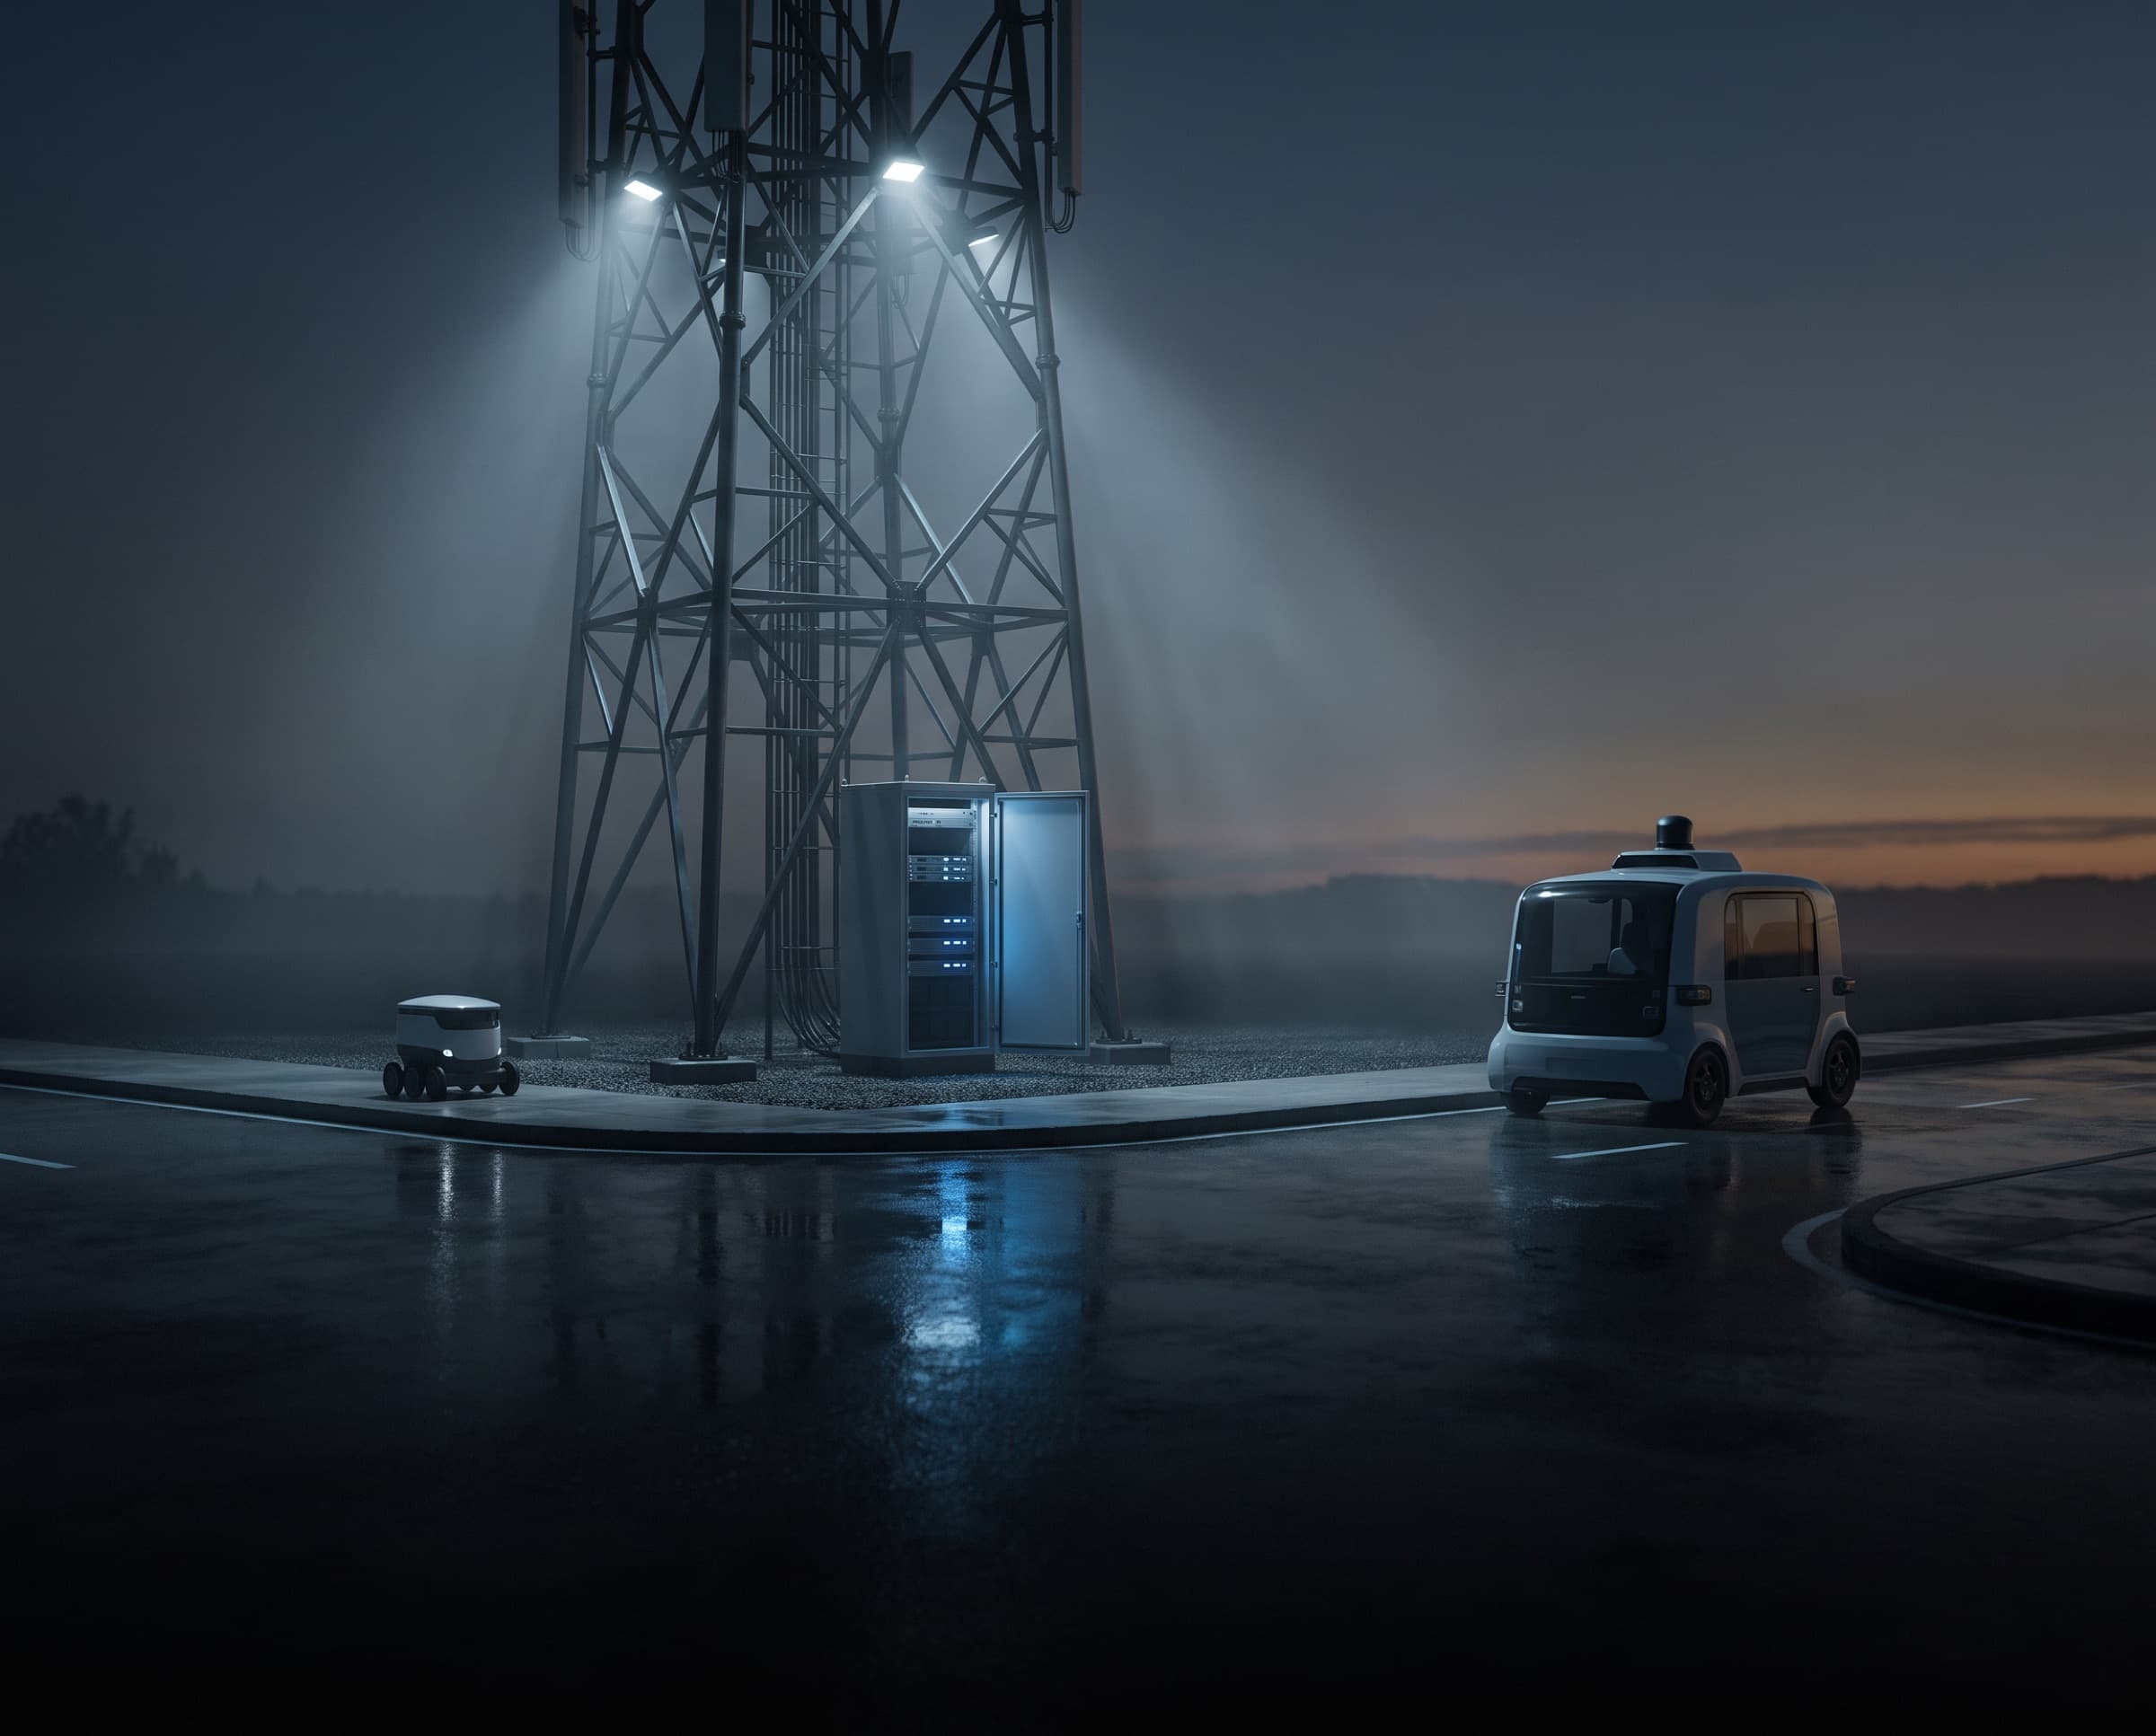
Inference at towers and ultra-edge facilities, under 100 ms, with no round trip to a distant cloud.
Bare-metal GPUs with a predictable PCIe topology and your own scheduling for safety-critical work.
At 60 mph a car covers 88 feet a second, so every millisecond of round trip is distance driven blind.
Single tenancy removes the performance swings, for systems where failure isn’t an option.
One deployment across cloud, edge and ultra-edge: train in the data center and infer at the edge, from development to production.
At 60 mph, a cloud round trip of 50–200 ms is 5 to 17 feet before the car can act. At the tower, the decision lands first.
An illustration at 60 mph, 88 feet a second: EdgeAI under its 100 ms, the cloud at the top of its 50–200 ms. The street is drawn; the blind part starts ten times slower than life, and the switch plays it in real time or slower.
Autonomous systems can’t wait for a round trip, or share their hardware with a stranger.
At the edgeCloud
Cloud inference takes 50–200 ms for the round trip. EdgeAI brings inference under 100 ms, at the edge, on hardware nobody else shares.
EdgeAI brings inference to towers, aggregation points and ultra-edge facilities.
One stack from connectivity (EdgeLink) to orchestration and deployment.
Distributed systems experience from running infrastructure at extreme scale, every day.
Every new edge location makes coverage denser and faster for everyone on it.
Talk to us